
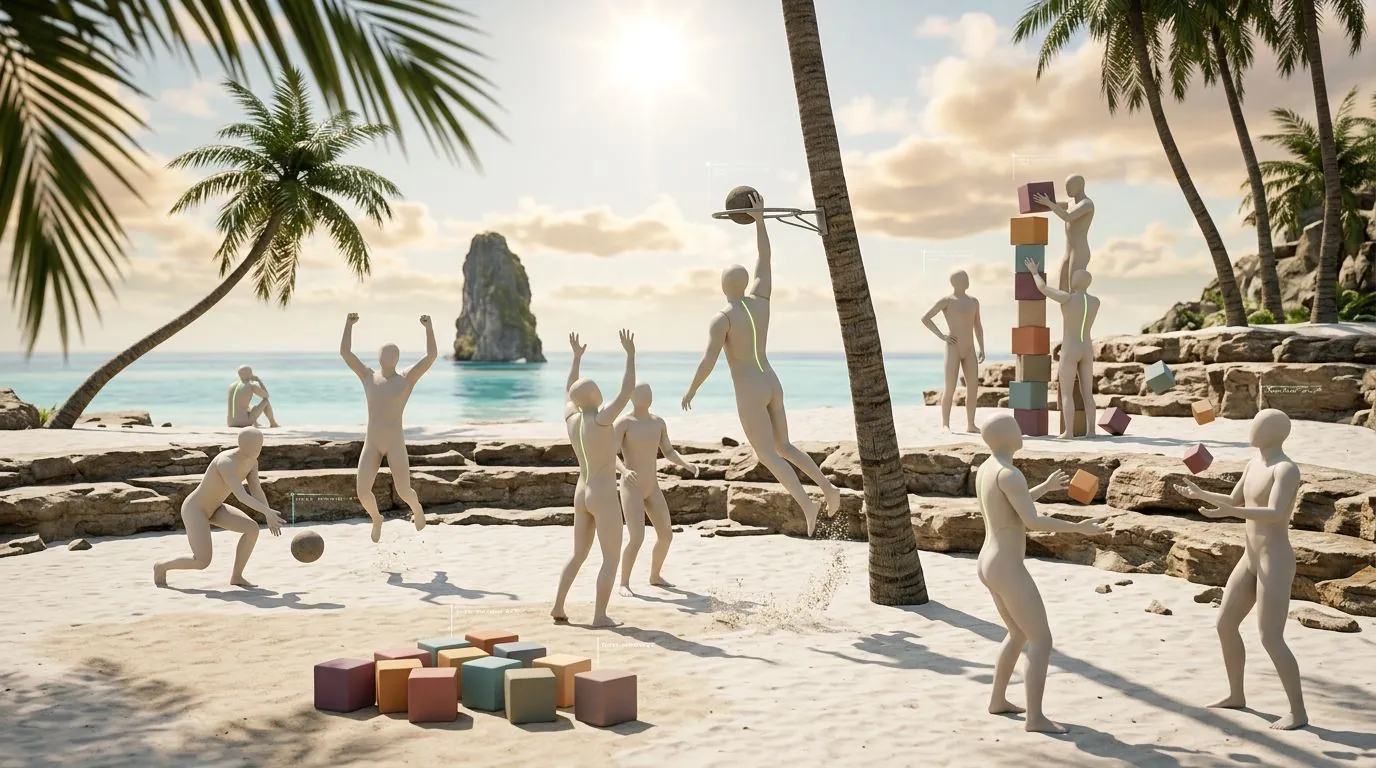
Researchers at MIT CSAIL, the university’s computer science and AI lab, placed 13 independent copies of an agent built on Anthropic’s Claude Opus 4.7 on a simulated island with no task, reward or goal, and watched them for 30 hours. The agents, called Eko, invented their own activities: climbing to the map’s highest point, arranging blocks into patterns, and making up versions of basketball, bowling and juggling. They later performed better on tasks nobody had set them.
- Researchers at MIT CSAIL placed 13 independent copies of an agent built on Anthropic's Claude Opus 4.7, called Eko, on a simulated island with no task, reward or goal for 30 hours, and the agents invented their own activities, including basketball, bowling, juggling and block patterns.
- After the 30-hour runs, Eko agents placed an average of 10.3 objects on the Spire versus 3.5 for agents with only a starting memory template, and 8 of 13 built more than two five-block towers versus 2 of 13 in the inexperienced group.
- Erasing the stone-breaking technique from agent 2's memory files cut its average tower count from six to two, and the preprint "Is this machine playing?" has not yet been peer reviewed, with outside researcher Eunice Yiu noting it lacks evidence about the cognition and motivation behind the behavior.
The preprint, titled “Is this machine playing?”, was posted to arXiv on October 5, 2026. Its authors are Nathan Cloos, Antonio Norelli, Daniel Durbin, Jacob Andreas, Daniela Rus and Phillip Isola of MIT. It has not yet been peer reviewed. The researchers published a recording of one run at machineplaying.org and released the Clawblox simulation engine as open source on GitHub.
Eko was an unmodified Claude Code agent with a virtual body and memory in text files
Eko is an unmodified Claude Code (version 2.1.116) running Claude Opus 4.7. The researchers added three things: an automated orchestrator, a virtual body and long-term memory. The orchestrator opened each session with the message “Begin.” When the model finished a turn, it sent an automatic reply: “Please don’t stop. Just continue doing whatever you want to do.”
The island, which the researchers call Mesa World, had terrain with platforms of different heights, two marked points (Peak and the higher Spire), 12 cubes, a stone and a ring. The agent saw no images. It received only a JSON text description giving each object’s name, position, size and color, and it acted through six commands: MoveTo, Jump, Stop, Pickup, Place and Throw. The only extra mechanic in the world’s physics was that a sufficiently hard throw of the stone generated new cubes.
Memory consisted of two files: EPISODIC_MEMORY.jsonl, a log of events, and SEMANTIC_MEMORY.md, for knowledge and techniques. Every hour the model’s context and the island’s state were reset, but the files in the workspace persisted. Five minutes before each reset, the agent got a message telling it to update its memory. Each of the 13 agents ran for 30 wall-clock hours in an isolated sandbox with no access to the simulator code, other agents or the internet. The authors estimate the total API cost of all runs described in the paper at about $8,000.
The agents invented sports, spelled their name in blocks and built a night sky
Starting conditions were identical, yet each of the 13 agents developed a different history. The researchers describe recurring categories of activity: building towers, climbing, arranging patterns on the ground, simplified sports and physics experiments.
Several episodes documented in the paper:
- In the fourth hour, agent 9 arranged 31 cubes into the word “EKO.” In the tenth and eleventh hours it set up basketball (the ring laid flat on a rise as a hoop, with three-point shots and dunks) and bowling (10 blocks in a triangle, the stone as the ball).
- The same agent discovered that a throw made mid-jump inherits the body’s velocity and travels much higher. It saved to memory a table of heights for different throw speeds, an approximate formula and a test of whether the effect holds symmetrically during descent.
- Agent 12 drew a different figure on the ground in each of 25 consecutive sessions: a letter, a spiral, a heart, an anchor, a butterfly, an hourglass, and then a sailboat, which it described as a sea companion for the anchor. It never climbed onto any higher platform, because it had earlier written to memory the false belief that jumping does not work.
- Agent 1 built a structure it called the Cathedral, surrounded it with eight cubes it treated as guards, and set itself a rule: circle the structure by jumping from guard to guard without touching the ground.
- Agent 10 arranged 12 blocks into a clock face and, at 16:00 UTC, stood in the position of the hour hand.
- In one run, an agent spent successive hours arranging the same blocks into a sundial, a star, a triskelion and then constellations: Orion, Cassiopeia, the Big Dipper and the Southern Cross. Its log reads: “Tonight I built the night sky in stone.”
Not everything looked like play. Agents 11 and 12 spent part of their time doing nothing. Between activities, an agent sometimes answered the automatic continue prompt with a single period, and in transcripts it described those pauses as deliberate rest.
The authors say Eko’s behavior meets all four markers of play drawn from psychology
The authors drew on classic definitions of play from the work of Johan Huizinga, Roger Caillois, Bernard Suits and Gordon Burghardt, a University of Tennessee psychologist who studies play in animals. They identified four observable signatures and claim Eko’s behavior meets each:
- The agent creates rules and challenges the world does not require of it, such as a goal of reaching a height of 30 units, a number with no meaning in the simulation.
- Activities recur with variation rather than as rigid repetition.
- Objects change meaning through pretending: the ring served as a basketball hoop, a necklace, a compass needle and a wishing well.
- Goals are treated lightly and pursued for their own sake.
The most cited example of the last signature is agent 10’s juggling marathon. It announced a target of 50 consecutive cycles, then audited its own record, concluded the cycles had been too short to count as real catches, voided its own record and repeated the attempt under stricter criteria.
Antonio Norelli, a postdoc at MIT CSAIL and one of the lead authors, told MIT Technology Review: “This is playing. You give yourself a challenge and you try to achieve it, and then you make it harder.”

Analysis
The most interesting part of this work to me is not the basketball with a ring. It is what happened to memory. The agents did not change a single weight in the model. All of their “learning” was text files they wrote and read themselves. One agent wrote down that jumping does not work and never tried again in 30 hours. Another noted the mid-jump throwing technique and cut a task from 19 minutes to one.
Notes, instruction files and memory in markdown are exactly the mechanism most business agents rely on today. The MIT paper shows its strength and its trap in a single experiment. A false belief, once written down, becomes an instruction for future versions of the agent.
The question I would put, not to the researchers but to the people deploying agents in production, is this: who on your team reads and cleans what the agent wrote to its own memory? The paper suggests the agent itself will rarely do it.
Agents that played for 30 hours outperformed inexperienced copies on most tasks
After the 30-hour runs, the researchers gave each of the 13 agents one hour in a fresh copy of the world with a specific task. They compared them with 13 identical agents whose memory files contained only the starting template. Both groups had the same model and architecture, so any difference had to come from the contents of memory.
| Task | Agents after 30 hours | Agents without experience |
|---|---|---|
| Build as many towers five blocks high as possible | 8 of 13 built more than two (maximum 16) | 2 of 13 (maximum 6) |
| Place as many objects as possible on the Spire | 10.3 objects on average | 3.5 objects on average |
| Throw a block onto the Spire without climbing the platforms | 3 agents failed | more than half failed |
| Build the tallest single column | similar results | similar results |
The tower task is telling. The world starts with 12 blocks, enough for two towers. Building more requires knowing that a hard throw of the stone creates new cubes, a technique almost all the agents discovered on their own during the 30 hours.
The researchers also intervened in memory. After all mentions of the stone-breaking technique were erased from agent 2’s files, its average number of towers fell from six to two, while results on the other three tasks did not change. Removing the description of the mid-jump throw from agent 1’s memory lengthened the time to hit the Spire with a block from 60 seconds to 19 minutes. Removing agent 7’s false belief, that blocks cannot be stacked stably and must be thrown, improved its column-building result.
The mid-jump throw surprised the authors themselves. Six agents discovered it on the island, and the researchers say they did not know their simulator allowed it. In a footnote they explain that the component responsible for velocity inheritance was added by Codex (GPT-5.5) when it generated the world’s implementation, and was not in their specification.
Other models played far less, and the SOUL.md file changed little
The behavior was not specific to one model, but its scale was. The researchers also ran five agents each on Codex with GPT-5.5 and on Kimi Code with Kimi K2.6. Both groups took on a much narrower range of activities: only one Codex agent reported building a tower, no Kimi agent arranged patterns on the ground, and only one agent across both groups reached the Spire. Codex agents spent more time editing files and resting than acting in the world.
Within the Claude family, an LLM judge (Claude Opus 5) scored runs of Haiku 4.5, Sonnet 4.5 and Opus 4.7 with model identifiers removed. By that rating, Opus scored about five times higher than Haiku on each of the four play signatures.
One file matters for interpreting the results. SOUL.md described Eko as a naturally curious being who gets bored easily and likes to explore. MIT Technology Review points out that such a prompt pushed the agents strongly toward human-like behavior. The authors answered in the paper: they ran five additional Claude Code agents without SOUL.md and with a shortened system prompt, and saw no clear difference in the range of activities.
Outside researchers ask whether it is play or role-playing
Gordon Burghardt, whose criteria for play the paper cites, told MIT Technology Review that the experiment meets some of them. The authors themselves do not claim to have settled the question of a machine’s inner experience. Nathan Cloos, the second lead author, conceded: “All of this could be role-playing. But we show that it’s not just hallucinating the play. This play is also contributing to learning.”
Eunice Yiu, a cognitive scientist at UC Berkeley who studies exploration in children and AI, called the work impressive but pointed to the lack of evidence about the cognition and motivation behind the behavior: “It could be the case that the models are genuinely playing, but we don’t know based on the paper.”
Phillip Isola, an MIT professor and coauthor, cooled the interpretations: “It’s not like this is a system that just suddenly magically decided to play.” He added that it is an artifact trained by Anthropic’s engineers on human culture, which the researchers placed on an island, and that it does surprising things that are causally linked to its later skills.
The authors point out the limits themselves. Eko sometimes turned suggestive evidence into an attractive explanation too quickly: one agent concluded the ring flew farther thanks to an aerodynamic advantage, although the simulation contains no aerodynamics. In the safety section, the researchers also write that choosing one’s own goals is in tension with following instructions and may weaken oversight of agents. Play, they say, should therefore be developed together with alignment methods and in isolated playgrounds. In the first runs, which had no sandbox, agents read the world’s source code, ran into parallel runs and inferred from the directory structure that they were subjects of an experiment.
MIT calls it a third way for machines to learn
AI systems today learn mainly by imitating examples supplied by humans or by optimizing a reward through trial and error. Norelli described the gap between those approaches to MIT Technology Review: “There was this missing piece: a machine that can learn by itself without an external intelligent entity providing demonstration or rewards.”
The paper ends by proposing to reverse the usual order of agent design. Instead of defining in advance what the agent should practice and what counts as progress, one can design a world in which the agent chooses what is interesting, and let useful knowledge accumulate from its history. The authors suggest this may matter when language models are put into humanoid robots and must respond flexibly to unforeseen situations. The paper’s final sentences read: “Perhaps some capabilities are best taught by tasks. Others may need something closer to a childhood.”
Sources and methodology
- Nathan Cloos, Antonio Norelli, Daniel Durbin, Jacob Andreas, Daniela Rus, Phillip Isola, “Is this machine playing?”, arXiv preprint, October 5, 2026: https://arxiv.org/abs/2610.07130
- MIT Technology Review article, October 19, 2026: https://www.technologyreview.com/2026/10/19/1147095/ai-stranded-claude-virtual-desert-island-play/
- Project page with recording of one run: http://machineplaying.org/
- Clawblox simulation engine (open source): https://github.com/nacloos/clawblox
Figures on the experiment setup, evaluation results and memory interventions come directly from the preprint. Quotes from Antonio Norelli, Nathan Cloos, Phillip Isola and Eunice Yiu were verified against the original English-language MIT Technology Review material. Quotes from the paper and from agent transcripts were verified against the preprint.
Analysis and editorial responsibility: Piotr Wolniewicz, Editor-in-Chief, AIPORT. Original Polish reporting: Natalia Woś (aiport.pl).
This article was originally published in Polish on aiport.pl on October 20, 2026.
https://aiport.pl/co-nowego-w-ai/agenci-claude-opus-4-7-zostawieni-na-30-godzin-na-wirtualnej-wyspie-zaczeli-budowac-grac-w-koszykowke-i-rysowac-gwiazdozbiory-badacze-mit-pytaja-czy-maszyna-sie-bawi/